Static frontends do not always need a permanent web-server pod. This case study explains how we replaced always-on Nginx workloads with short-lived synchronization jobs, versioned object storage, and a shared read-only delivery gateway while preserving GitOps deployment and rollback safety.
- Primary Domain
- Kubernetes & GitOps
- System Scope
- Baremetal Production Forensics
- Telemetry Standard
- Deterministic Verification
The short version
Static frontends rarely need a permanent web-server process. Most of the time, no frontend pod needs to run continuously. We kept the essential elements of GitOps—version control, automated review, immutable builds, and declarative reconciliation—while eliminating the operational cost of running idle Nginx pods 24/7.
The important lesson is not simply "put static files in object storage". The useful work was defining clean delivery, synchronization, rollback, routing, and access boundaries around that change.
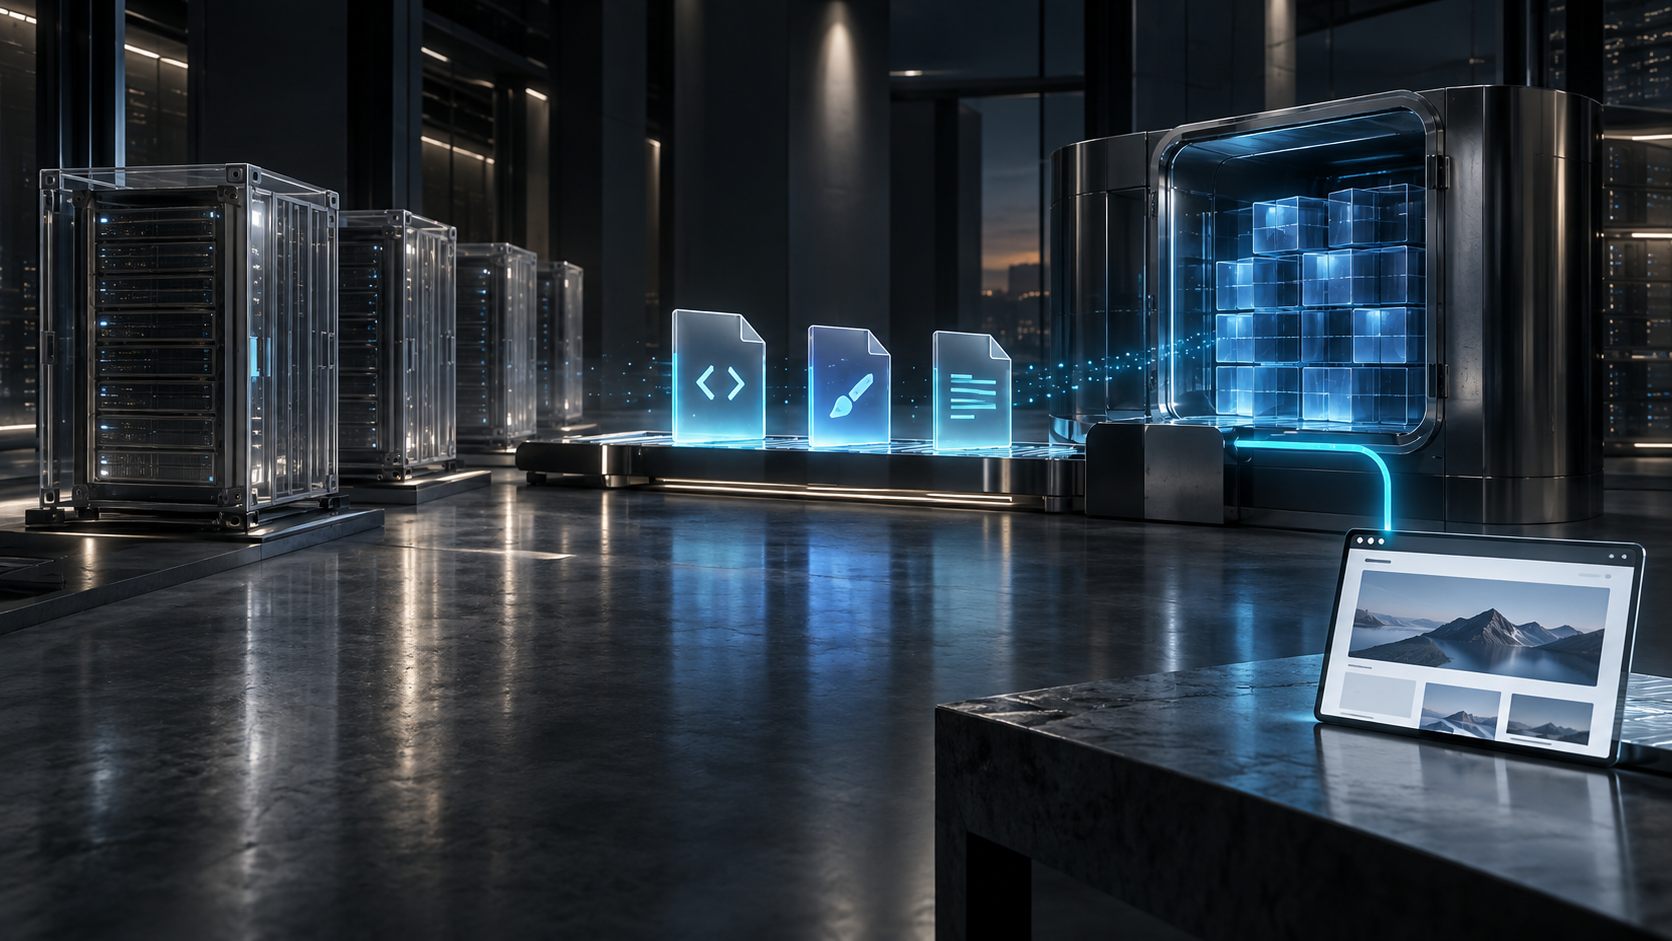
Static site image, synchronization, and delivery planes
The separation of delivery and publishing
The core architectural change was decoupling the public read path from the background synchronization path:
• The delivery plane serves immutable static assets through a cache-aware edge gateway. - The publishing plane synchronizes compiled assets to object storage via authenticated build and release tooling.
This separation establishes defense-in-depth: the edge delivery path is decoupled from deployment pipelines, preventing asset ingestion from sharing code or credential boundaries with public browsing traffic.
CI, Jobs, and approved operator tooling write directly to private S3-compatible endpoints with scoped credentials, keeping publishing completely separate from edge request serving.
Host-based static routing
Removing frontend pods did not require redesigning ingress architecture.
Host-based routing is decoupled from individual web-server runtimes. Rather than running a dedicated server container per domain, ingress routing maps incoming hostnames to corresponding object storage namespaces or buckets, applying caching policies and client-side single-page application fallback rules.
For deliberate aliases, multiple hostnames can map to a canonical bucket, avoiding duplicated assets while preserving clean ownership.
Dynamic application endpoints remain routed with explicit path precedence to dedicated backend services, ensuring that static asset delivery and transactional API traffic remain completely independent.
The resulting request paths are intentionally segregated:
That clean separation makes both planes significantly easier to reason about and secure.
browser -> ingress -> shared static gateway -> object storage
browser -> ingress -> dynamic API service -> persistent application data
Rollback safety with versioning
Object synchronization can overwrite a file or place a delete marker on an object. Without versioning, a bad build can destroy the last known-good copy before anyone notices.
We enabled object versioning before synchronization. Each overwrite creates a new version, and deletion no longer immediately destroys the previous bytes. This provides a storage-level recovery option in addition to rebuilding an older image.
Versioning is not free retention. Frequently changing bundles can create many noncurrent versions, especially for stable filenames such as index.html. We paired versioning with lifecycle management so old noncurrent versions and expired delete markers are removed after a bounded recovery window.
This gives us three rollback paths:
1. run the synchronization Job with a previously known-good image; 2. restore selected object versions when only a few files are affected; or 3. rebuild and publish from a reverted source commit.
The exact retention window is an operational choice. The important part is pairing recoverability with a limit, rather than choosing between permanent history and immediate destruction.
Migration without a large cutover
We moved the sites in small groups.
For each site we followed the same sequence:
1. Build the existing frontend image and verify its compiled directory. 2. Create the synchronization Job without removing the Deployment. 3. Populate the destination bucket and compare representative assets. 4. Route a test or secondary hostname through the shared gateway. 5. Validate HTML fallback, asset content types, cache headers, and API path precedence. 6. Switch the primary route. 7. Remove the now-unused frontend Deployment only after the object path was healthy.
We also rendered every changed manifest before rollout and checked that GitOps health rules no longer expected the retired Deployment.
This staged approach mattered because a static homepage returning HTTP 200 is not enough. A valid migration must also verify deep links, JavaScript chunks, CSS, images, canonical redirects, client-side routing, and any paths reserved for APIs or generated content.
What improved
The most visible result was the absence of permanent frontend pods. That also removed their steady resource reservations and reduced the number of rollouts, probes, endpoint updates, and restart events the platform had to process.
Other improvements were less obvious but more important:
• Static delivery now has one consistent cache and fallback implementation. - Public reads and authenticated writes have separate paths. - Bucket versioning provides recovery from overwrites and deletions. - Lifecycle policy prevents rollback history from growing forever. - Dual-hosted sites can share one canonical copy of their assets. - Dynamic APIs have explicit routes and independent availability. - The same frontend image can still be run locally for testing or extracted by the deployment Job.
We did not remove operational responsibility. We changed its shape. Instead of watching many idle web-server pods, we now watch synchronization success, object-store health, gateway behaviour, and version-retention policy.
Trade-offs and failure modes
This pattern is not a universal replacement for frontend Deployments.
It is a poor fit when the application requires server-side rendering, runtime authentication inside the frontend process, request-time personalization, WebSockets, or application-specific server middleware.
It also introduces different failure modes:
• A successful image build can still be followed by a failed synchronization. - A broad delete operation can remove data outside the build's ownership. - Incorrect content types or cache policy can break browsers even when objects exist. - A shared gateway increases the importance of careful host isolation. - Versioning without lifecycle policy can quietly consume storage. - Static HTML may lag behind dynamic content unless the publication workflow triggers a rebuild.
The design is worthwhile only when these risks are treated as first-class deployment concerns.
Practical decision guide
Keep a dedicated frontend runtime when:
• pages are rendered or personalized per request; - the server enforces application logic; - deployment and serving must be one atomic process; or - the site needs runtime features that object delivery cannot provide.
Consider ephemeral synchronization and shared object delivery when:
• the final output is a directory of immutable files; - releases are less frequent than reads; - multiple small static frontends repeat the same web-server pattern; - the platform already operates reliable S3-compatible storage; and - clear ownership and rollback rules can be established.
Primary references
• Kubernetes Jobs and CronJobs for bounded, retryable execution. - Kubernetes Deployments for the long-running workload model being replaced. - Amazon S3 Versioning for overwrite and deletion recovery semantics. - Amazon S3 Lifecycle for bounded retention of noncurrent objects.
Closing lesson
The waste was not Nginx itself. Nginx is an excellent static server. The waste came from keeping one copy running for every bundle when a shared delivery layer could serve the same immutable files.
The successful migration depended on four boundaries:
1. container images remained build artifacts; 2. synchronization Jobs became short-lived publishers; 3. object storage became the durable, versioned source for static delivery; and 4. the delivery plane remained decoupled from backend publishing and dynamic application APIs.
That combination removed idle compute without turning deployment into an untracked file copy. The sites still follow GitOps. They simply stop consuming Kubernetes runtime resources when there is no code to run.
Need a second opinion on Kubernetes storage, HA, or telemetry architecture?
I help platform engineering teams identify redundant storage layers, eliminate latency bottlenecks, and harden high-concurrency production platforms against silent failure modes.